WordPress Site Health loopback failure: check the route
A visitor’s browser reaches your WordPress site from outside. It follows public DNS, passes through whatever CDN, firewall or hosting layer is in front, and loads the homepage. For a Dubai or UK service business, that is the route customers use, so it is understandably the one people check first.
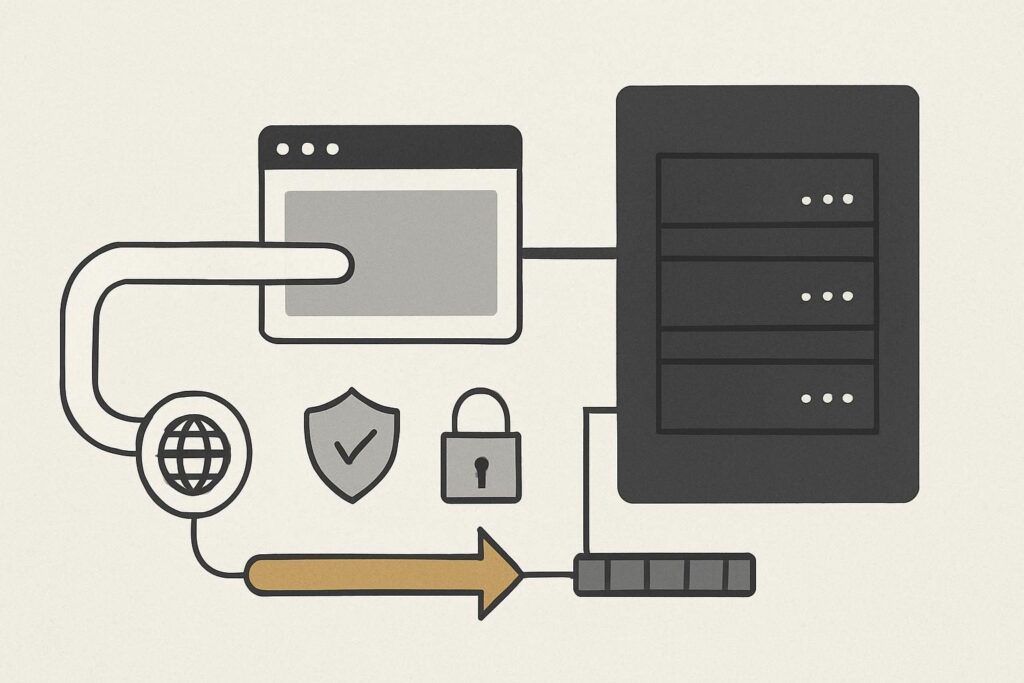
The website server making a request back to its own address is a different caller. It may use a different DNS answer, hit a private address, meet a staging login prompt, fail certificate validation or be rejected by a security rule. Same domain. Different journey.
If WordPress Site Health reports a failed loopback request while the homepage loads, do not treat the warning as decorative, but do not start disabling plugins at random either. The useful question is whether the server can reach the WordPress endpoint Site Health is testing, and what response comes back.
Read the response before changing the protection
WordPress Site Health performs a request back to the site, then evaluates transport errors and the HTTP response status. That check is not the same as opening a homepage in a browser. The method is documented in the WordPress Site Health loopback request reference.
A failed loopback can matter because parts of WordPress that depend on internal requests or background processing may be less dependable than the visible front end suggests. It is worth treating as a focused WordPress website repair investigation, rather than a reason to broadly weaken server protection.
WordPress Site Health loopback failures usually mean the server cannot successfully request its own WordPress URL under the conditions used by that request. The cause may be HTTP authentication, DNS resolution, TLS verification, a web application firewall, a proxy rule or an unexpected HTTP response. A browser loading the homepage only proves the visitor route works. It does not prove the server-to-site route works.
Start with the result Site Health actually reports
Preserve the exact message, response code and error wording before any settings are changed. A timeout, 401 response, 403 response and certificate error point in rather different directions.
- Connection or timeout error: inspect server-side DNS, routing and firewall behaviour.
- 401 or 403 response: inspect HTTP authentication, security plugins, WAF policy and access rules.
- TLS or certificate error: inspect the certificate chain and hostname seen from the server.
- Unexpected HTTP status: identify the endpoint requested and find which layer generated the response.
The endpoint matters. Site Health is not simply asking for the public homepage and giving it a once-over. It makes a loopback request through WordPress, so retain the reported URL and status rather than testing a vaguely similar address in a browser.
A staging site can pass the eye test and fail the loopback
A common illustrative case is a staging copy protected with HTTP authentication. Staff open it fine because their browser has the username and password, or because they are already prompted for them. Site Health then makes its server-side request without the same browser context and receives a 401 response.
That does not automatically mean staging protection should be removed. It means the access boundary needs examining properly. Is the authentication rule intended to cover all callers? Is there a safe, limited exception for the specific internal route? Is WordPress using the expected site URL? A WordPress staging site setup checklist is useful when that staging copy has acquired several layers of access control over time, which is common enough after a rushed launch or migration.
Trace the server-to-site route in order
- Identify the caller. Confirm the request originates from the web server or PHP environment, not your office browser or a mobile connection.
- Confirm the target. Check the WordPress home and site URLs, the hostname used in the reported result, and whether the server resolves that hostname as expected.
- Inspect the access boundary. Review basic authentication, host firewall rules, WAF events, security plugin controls and proxy restrictions that could treat an internal request differently.
- Compare TLS behaviour. Ensure the hostname, certificate and chain presented on the internal route are valid for that route too.
- Make one narrow correction. Adjust the rule that evidence points to, rather than allow every request from everywhere because one health check complained.
- Retest Site Health and the affected function. A cleared warning is useful, but the background activity that raised concern should be checked as well.
That last part is where repairs often get a bit woolly. A security exception that clears the Site Health notice but leaves a protected staging site publicly exposed is not a fix. It is paperwork disguised as progress.
Keep loopback diagnosis separate from scheduling
A loopback warning may sit alongside missed scheduled posts, delayed imports or jobs that appear not to run, but it does not prove which part has failed. Scheduling configuration, traffic-dependent cron execution and a specific failed task are adjacent questions. If the real symptom is scheduled content or background jobs not firing, use the separate checks for WordPress scheduled posts and cron jobs not running after the self-request route has been understood.
The clear recommendation is simple: capture the exact Site Health response, trace the server’s own route to the named endpoint, and change only the boundary responsible for the failure. It is slower than ticking every security setting off and on, but considerably less likely to leave a new problem behind.
If you need a second pair of eyes, send the exact Site Health loopback result so the server-to-site route can be investigated. Include the error wording, affected URL, whether the site is live or staging, and any recent DNS, SSL, firewall or authentication changes.